For the complete documentation index, see llms.txt. Markdown versions of all docs pages are available by appending .md to any docs URL.
Virtual keys
Protect provider credentials with virtual keys, then add optional token budgets and usage tracking.
Keep provider API keys on the gateway and give each client a revocable virtual key. Add token budgets and usage tracking as needed.
About
Clients use virtual keys to authenticate to agentgateway. The gateway replaces each virtual key with the provider key before forwarding the request. Clients never receive the provider key, and the provider never receives the virtual key.
Each client has its own key, so you can revoke one client’s access without rotating the provider key or reconfiguring other clients. Provider-key rotation happens on the gateway host.
How virtual keys work
    sequenceDiagram
    participant C as Client<br/>(holds a virtual key)
    participant AGW as Agentgateway<br/>(holds the provider key)
    participant P as LLM provider
    C->>AGW: Request with the virtual key
    AGW->>AGW: Validate the key and check model access
    AGW->>AGW: Replace the virtual key with the provider key
    AGW->>P: Request with the provider key
    P-->>AGW: Response
    AGW-->>C: Response
Security considerations
The gateway host holds every provider key. Protect it as you would any other secret store.
- Restrict access to the files. Run agentgateway as a dedicated user, and make the key file and the configuration file readable only by that user.
- Do not store raw virtual keys. Store a
keyHashfor each virtual key instead of the rawkey, so that a copy of the configuration file does not contain usable keys. - Encrypt client traffic. Virtual keys are bearer credentials. Serve clients over TLS, or keep the gateway on a private network.
- Protect the UI and admin API. Anyone who can reach them can create and read virtual keys. For more information, see Secure the UI.
- Keep agentgateway up to date with security patches.
Before you begin
Install theagentgateway binary.You also need an OpenAI API key. The examples read it from OPENAI_API_KEY. For file-based credentials and rotation without a restart, see Provider API keys.
Note
Set up virtual keys (UI)
Set up virtual keys interactively through the UI.
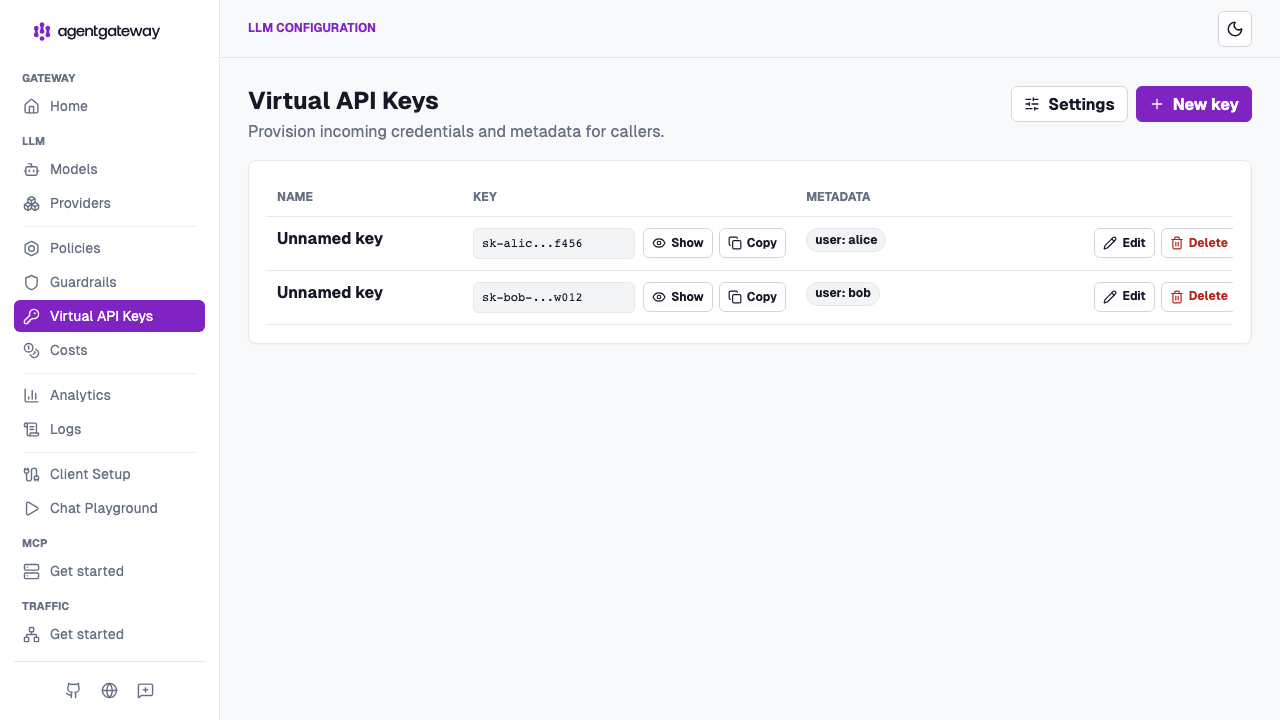
Open http://localhost:15000/ui/llm/keys (LLM > Virtual API Keys). Configured keys and their metadata are listed here, where you can show, copy, edit, or delete each one.
Click New key. Give the key a name, let agentgateway auto-generate the key value (or paste your own), and add metadata such as a
userentry to attribute usage. Click Save key.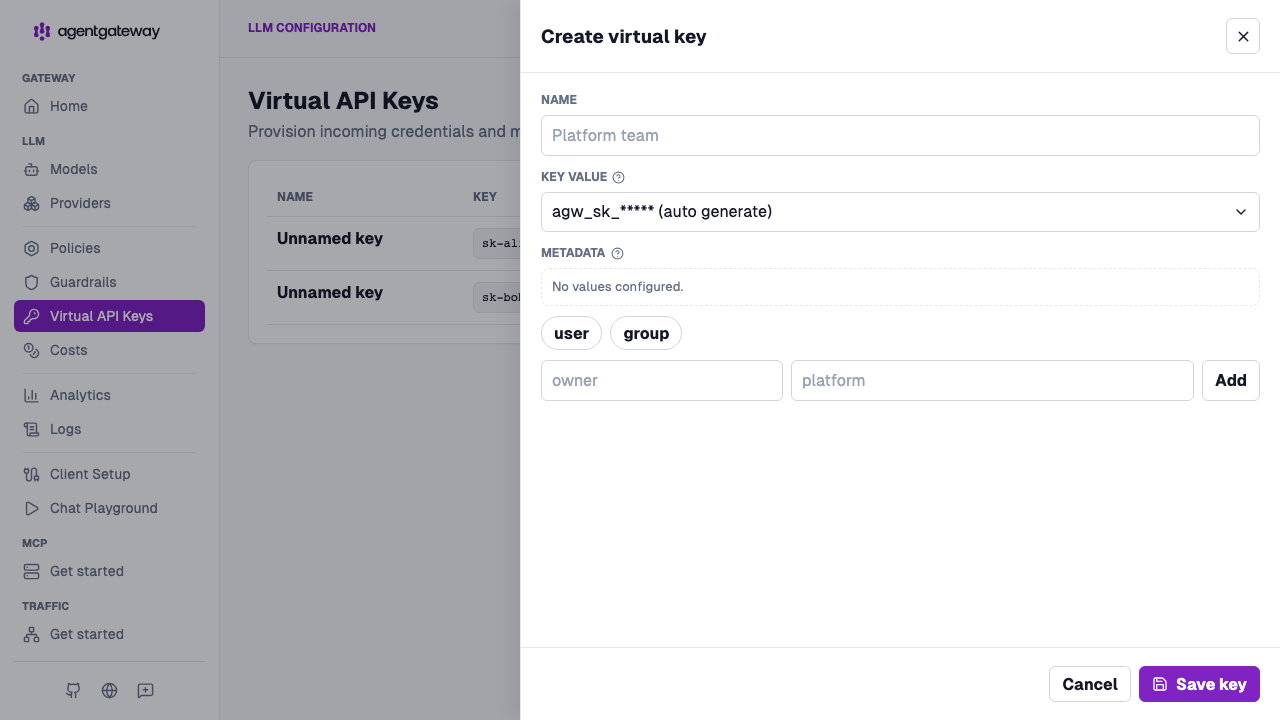
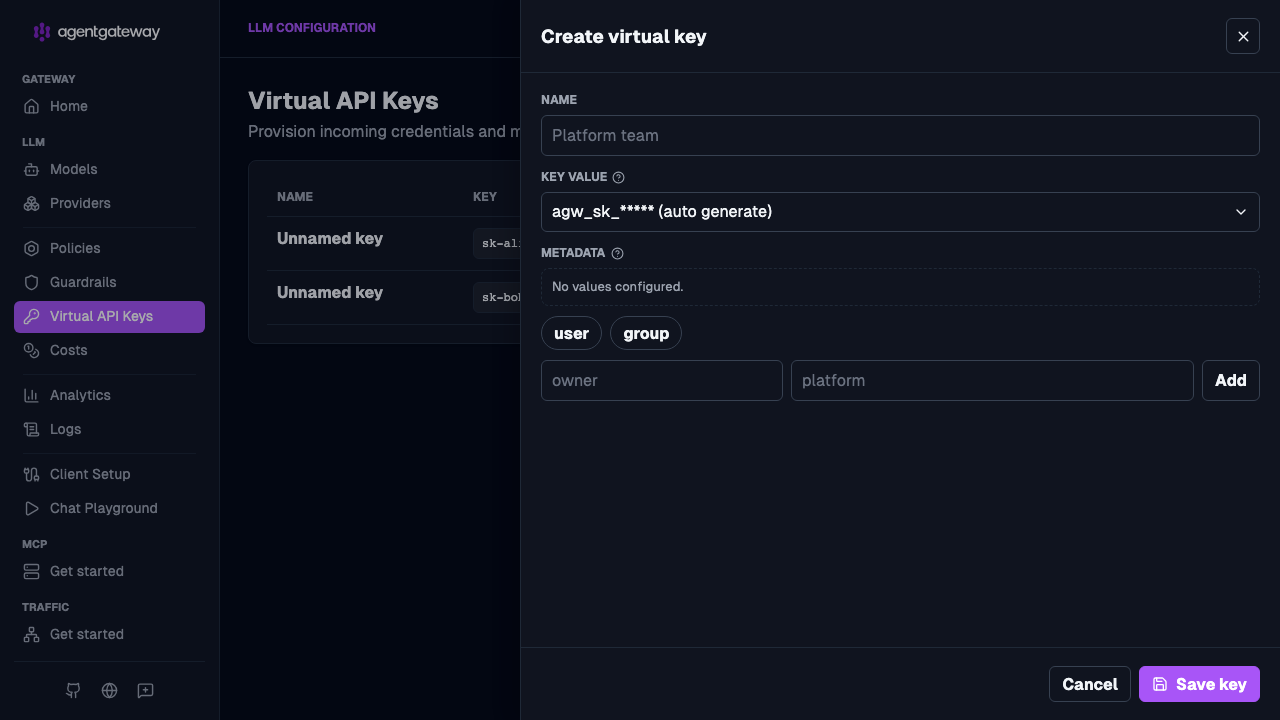
Copy the virtual key value. Give this key to your users to use in an
Authorization: Bearer $VIRTUAL_KEYheader in subsequent requests through agentgateway.
The rest of this guide uses the equivalent config-file settings, which apply the same apiKey policy shown in the UI.
Set up virtual keys (config file)
Set up virtual keys in a declarative config file, particularly useful in GitOps settings.
Step 1: Configure API key authentication
Create a configuration with API key authentication. This example creates two virtual keys for Alice and Bob.
cat <<'EOF' > config.yaml
# yaml-language-server: $schema=https://agentgateway.dev/schema/config

llm:
  policies:
    apiKey:
      mode: strict
      keys:
      - key: vk-alice-4f9c2a
        metadata:
          user: alice
      - key: vk-bob-8d1e7b
        metadata:
          user: bob
  models:
  - name: "*"
    provider: openAI
    params:
      apiKey: "$OPENAI_API_KEY"
EOF| Setting | Description |
|---|---|
apiKey.mode | The API key authentication mode. strict requires a valid API key for all requests. optional (default) validates the key if one is present but allows unauthenticated requests. permissive never rejects requests, which is useful when later steps such as authorization or logging rely on API key claims. |
apiKey.keys | List of API keys. Each key has a key value and optional metadata. |
key | The API key value that users include in the Authorization: Bearer <key> header. |
metadata | Optional metadata associated with the key, such as a user identifier or tier. |
models[].name | The models that the gateway serves. Use * for all provider models, or list model names to restrict access. For per-key restrictions, see Restrict model access. |
params.apiKey | The provider key that replaces the virtual key in outgoing requests. For file-based rotation without a restart, see Rotate a provider key. |
Step 2: Start agentgateway
agentgateway -f config.yamlStep 3: Test the virtual keys
Send a request with Alice’s API key. Verify that the request succeeds.
curl -s http://localhost:4000/v1/chat/completions \
  -H "Authorization: Bearer vk-alice-4f9c2a" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gpt-3.5-turbo",
    "messages": [{"role": "user", "content": "Hello!"}]
  }' | jq .
Example successful response:
{
  "choices": [{
    "message": {
      "role": "assistant",
      "content": "Hello! How can I help you today?"
    }
  }],
  "usage": {
    "prompt_tokens": 10,
    "completion_tokens": 9,
    "total_tokens": 19
  }
}
Send a request without a valid API key. Verify that the request is rejected with a 401 status.
curl -s -o /dev/null -w "%{http_code}" http://localhost:4000/v1/chat/completions \
  -H "Authorization: Bearer invalid-key" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gpt-3.5-turbo",
    "messages": [{"role": "user", "content": "Hello!"}]
  }'
Expected response:
HTTP/1.1 401 Unauthorized
Manage client access
Control access for individual clients without reconfiguring the others. You can also rotate the provider key without changing any client.
Restrict model access
The * model serves every model the provider offers. To restrict access for all clients, replace it with named model entries.
To restrict a specific key, add
allowedModelsto that key. This example keeps Bob’s access to the model used by this guide.keys: - key: vk-alice-4f9c2a metadata: user: alice - key: vk-bob-8d1e7b metadata: user: bob allowedModels: - gpt-3.5-turboSend a request with Bob’s key for a model outside
allowedModels. Verify that agentgateway returns403. Requests for a model absent fromllm.modelsget404.curl -s http://localhost:4000/v1/chat/completions \ -H "Authorization: Bearer vk-bob-8d1e7b" \ -H "Content-Type: application/json" \ -d '{"model": "gpt-4o", "messages": [{"role": "user", "content": "Hello!"}]}'Example output:
{"error":{"message":"Model is not allowed for this API key","type":"invalid_request_error","code":"model_not_allowed"}}
For model patterns and budget interactions, see Limit model access per key.
Revoke a virtual key
Revoke one client’s access without restarting agentgateway or changing other keys.
Remove Bob’s entry from
llm.policies.apiKey.keysand save the configuration. Keep Alice’s entry:keys: - key: vk-alice-4f9c2a metadata: user: aliceSend a request with Bob’s key. Verify that agentgateway returns
401.curl -s -o /dev/null -w "%{http_code}\n" http://localhost:4000/v1/chat/completions \ -H "Authorization: Bearer vk-bob-8d1e7b" \ -H "Content-Type: application/json" \ -d '{"model": "gpt-3.5-turbo", "messages": [{"role": "user", "content": "Hello!"}]}'Example output:
401Restore Bob’s key before continuing with the budget examples.
Rotate a provider key
Replace the provider credential on the gateway host. Clients keep their virtual keys.
- Follow Rotate a provider key to replace the credential and revoke the old provider key.
- Send a request with an existing virtual key. Verify that it still succeeds.
Set up virtual keys (agctl)
Generate, restrict, update, and revoke virtual keys from the command line with agctl standalone. The CLI can also give each key a dollar or token budget, and report the budget usage and spending of each key. Before you begin, install agctl.
Step 1: Configure the gateway
Create a separate configuration file with a database and an API key policy that has no keys yet. The database stores the budget usage of each key, and records LLM requests for analytics. In the default
filestorage mode, the CLI writes the keys that you create into this configuration file.cat <<'EOF' > config-agctl.yaml # yaml-language-server: $schema=https://agentgateway.dev/schema/config config: database: url: sqlite://virtual-keys.db llm: policies: apiKey: mode: strict keys: [] models: - name: "*" provider: openAI params: apiKey: "$OPENAI_API_KEY" EOFSetting Description config.database.urlThe database that stores budget usage and request logs. A budget requires this field. Setting only config.logging.database.urldoes not meet this requirement.apiKey.keysThe keys that you define in the file. Start with an empty list, and create the keys with the CLI. Start agentgateway. If agentgateway still runs from a previous section, stop it first. Keep agentgateway running, and run the CLI commands in another terminal.
agentgateway -f config-agctl.yaml
Step 2: Create a key
The CLI prints the generated key once, and stores only a SHA-256 hash of the key. You cannot retrieve the key later.
Create a key named
team-athat can usegpt-4omodels and has a daily token budget. The command saves the key in theVIRTUAL_KEYenvironment variable.VIRTUAL_KEY="$(agctl standalone keys create team-a \ --model 'gpt-4o*' \ --budget 1000tokens/24h \ --budget-action block)"Example output:
API key "team-a" created. Save it now; it cannot be shown again.The
VIRTUAL_KEYvariable exists only in your current shell. Before you close the terminal, store the key somewhere safe, such as a secrets manager, and give it to the client that uses it.Flag Description --modelA model name or wildcard pattern that the key can use, such as gpt-4o*. Repeat the flag for several patterns. If you omit the flag, the key can use every model.--budgetThe amount and window of a budget, such as 1000tokens/24hor10usd/24h. If you omit the window, it defaults to30d. Repeat the flag to add independent budgets. The CLI names each budget after its unit and window, such astokens-24h. Ausdbudget charges a request only if the model cost catalog prices its model.--budget-actionblockrejects requests after the key uses up a budget. The default,audit, records the overage but allows the requests.List the keys. The
KEYcolumn shows a hint of the key, not the full value.agctl standalone keysExample output:
NAME    KEY             MODELS   BUDGETS          CREATED           ID
team-a  agw_sk_...8mk2  gpt-4o*  1000 tokens/24h  2026-10-20 15:50  2672111b-2804-471c-8575-763e41c2d91c
Budget windows are aligned to the Unix epoch, not to the time that you create the key. For more information about how budgets charge requests, see Per-key budgets.
Step 3: Test the key
Send a request for a model that the key can use. Agentgateway forwards the request to the provider, and charges the token usage of the response to the budget of the key. If the request returns a
401status right after you create the key, retry the request. New keys reach the traffic path asynchronously.curl -s http://localhost:4000/v1/chat/completions \ -H "Authorization: Bearer $VIRTUAL_KEY" \ -H 'Content-Type: application/json' \ -d '{"model":"gpt-4o-mini","messages":[{"role":"user","content":"Hello!"}]}'Example output:
{
  "model": "gpt-4o-mini",
  "choices": [{
    "message": {
      "role": "assistant",
      "content": "Hello! How can I help you today?"
    }
  }],
  "usage": {
    "prompt_tokens": 10,
    "completion_tokens": 9,
    "total_tokens": 19
  }
}
Send a request for a model that the key cannot use. Agentgateway rejects the request with a
403status before the request reaches the provider.curl -s http://localhost:4000/v1/chat/completions \ -H "Authorization: Bearer $VIRTUAL_KEY" \ -H 'Content-Type: application/json' \ -d '{"model":"gpt-5","messages":[{"role":"user","content":"Hello!"}]}'Example output:
{"error":{"message":"Model is not allowed for this API key","type":"invalid_request_error","code":"model_not_allowed"}}
Step 4: Check usage and spending
Check the budget usage of the key. To list the budgets of every key, omit the
--keyflag.agctl standalone budgets --key team-aExample output:
KEY     BUDGET      USED       LIMIT        REMAINING   RESETS            STATUS  ACTION
team-a  tokens-24h  19 tokens  1000 tokens  981 tokens  2026-10-20 20:00  ok      block
The
RESETScolumn shows the end of the current window in your local time. The command reports per-key budgets only, notlocalRateLimittoken buckets.Summarize the requests, tokens, and cost of each user. The rejected request from the previous step counts as an error.
agctl standalone analytics --by agentgateway.user --since 24hExample output:
AGENTGATEWAY.USER  REQUESTS  ERRORS  TOKENS  COST       AVG TTFT  TOK/S  CACHE HIT
team-a             2         1       19      $0.000007  -         -      0.0%
Agentgateway attributes each request to the
userornamemetadata of the key. For more groupings, see CLI analytics.List the requests that agentgateway recorded.
agctl standalone logs --since 1hExample output:
TIME                 STATUS  DURATION  PROVIDER  MODEL        TOKENS(IN/OUT)  COST       ID
2026-10-20 15:50:34  200     1ms       openai    gpt-4o-mini  10/9            $0.000007  01a15add-9aa1-73ee-bc2a-b7fe5c9a70a6
2026-10-20 15:50:34  403     0ms       -         -            -               -          01a15add-9aba-720e-a3dd-a11287a94806
For filters and request details, see View LLM request logs with agctl.
Step 5: Update a key
To change the metadata, model restrictions, or budgets of a key without changing the key itself, export the key, edit it, and apply it again. The update replaces the whole value of the key, so keep every field that you want to retain.
Export the key.
agctl standalone get llm.apiKey team-a -o yaml --no-metadata > team-a.yamlEdit
team-a.yaml. For example, addgroup: engineeringundervalue.metadata. Keep the top-levelid, thevalue.keyHashfield, and the existing metadata. Do not change the metadata fields that start withagentgateway.dev/. To change a budget, edit itsvalue.budgets[].limit.amountfield. Keep the name and window of the budget so that agentgateway keeps its usage count.Apply the update.
agctl standalone apply -f team-a.yamlExample output:
llm.apiKey/2672111b-2804-471c-8575-763e41c2d91c applied
The key in VIRTUAL_KEY still works, because its hash did not change. The keys create command has no flags for other metadata, such as user or group. To add this metadata to a key, use this update workflow.
Step 6: Revoke a key
Delete the key by name. If several keys have the same name, use the ID from
agctl standalone keysinstead.agctl standalone delete llm.apiKey team-aExample output:
llm.apiKey/team-a deletedRepeat the request from Step 3. Agentgateway rejects the request with a
401status. Requests that are already in progress when you delete the key can still complete.Example output:
api key authentication failure: invalid credentials
To rotate a key, create a replacement key with a new name, update the client, and then revoke the old key.
Configure token budgets
Token budgets are optional. Continue here to limit token usage across clients, then give each key its own budget. Keep your existing keys, provider credentials, and model restrictions when adding these policies.
Warning
localRateLimit is a gateway-wide limit, not a per-key limit. It enforces a single shared token budget across all requests and API keys. To give each virtual key its own budget instead, add a key field to the rule, as shown in Step 4.
How rate limiting works
Agentgateway checks token-based rate limits in two phases:
At request time:
- When
tokenize: trueis not set or is set tofalseon the AI backend, the number of tokens that are used for the request cannot be calculated. Because of this, the request is always allowed, unless the rate limit is set to 0 tokens. The LLM typically returns the number of tokens that were used for the request when sending the response. Agentgateway verifies the number of tokens that were used in the request and the response to determine whether the rate limit was reached. By default,tokenizeis set to false. - When
tokenize: trueis set, agentgateway estimates the number of tokens at request time. Because of that, the request is only allowed if the estimated number of tokens does not exceed the set rate limit.
At response time:
When the LLM returns a response, it typically provides the number of tokens that were used during the request and response. Agentgateway uses these numbers to determine if the rate limit was reached.
Note that this determination happens after the response is returned. Even, if the number of tokens that are used in the response exceeds the number of allowed tokens, the response is still returned to the user. Only subsequent requests are rate limited. If tokenize: true is set on the AI backend and tokens were estimated during the request, agentgateway verifies the actual number of tokens that were used for the request when the LLM returns its response. In the case the initial estimation was off, agentgateway adjusts the number of used tokens to count these against the set rate limit.
Step 1: Add a token budget
Add localRateLimit under llm.policies in config.yaml. Keep the existing apiKey policy and model configuration.
llm:
  policies:
    localRateLimit:
    - maxTokens: 10
      tokensPerFill: 1
      fillInterval: 60s
type: tokens| Setting | Description |
|---|---|
localRateLimit | Applies a token-based rate limit to all incoming LLM requests. |
maxTokens | The maximum number of tokens that are available to use. |
tokensPerFill | The number of tokens that are added during a refill. |
fillInterval | The number of seconds after which the token bucket is refilled. |
type | The type of rate limiting to apply. Use tokens for token-based rate limiting, or requests for request-based rate limiting. |
Step 2: Verify rate limits
Start agentgateway with the updated configuration.
agentgateway -f config.yamlSend a prompt to the LLM. At the time the prompt is sent, the number of tokens required for the completion is unknown. Make sure to include a virtual key in the authorization header. Because
tokenize: trueis not set on the model, the prompt count is not estimated. As a result, the prompt is allowed.Note
The LLM typically returns the number of tokens required for completion in its response. Agentgateway uses this number and counts it against the rate limit.
curl http://localhost:4000/v1/chat/completions \
  -H 'Content-Type: application/json' \
  -H 'Authorization: Bearer vk-alice-4f9c2a' \
  -d '{
    "model": "gpt-3.5-turbo",
    "messages": [
      {
        "role": "user",
        "content": "Tell me a short story"
      }
    ]
  }'
Example output:
{
  "choices": [
    {
      "message": {
        "content": "Once upon a time, in a small village nestled between towering mountains...",
        "role": "assistant"
      },
      "finish_reason": "stop"
    }
  ],
  "usage": {
    "prompt_tokens": 12,
    "completion_tokens": 248,
    "total_tokens": 260
  }
}
Repeat the same request. This time, the request is rate limited because the tokens used in the first request exceeded the budget.
curl http://localhost:4000/v1/chat/completions \
  -H 'Content-Type: application/json' \
  -H 'Authorization: Bearer vk-alice-4f9c2a' \
  -d '{
    "model": "gpt-3.5-turbo",
    "messages": [
      {
        "role": "user",
        "content": "Tell me a short story"
      }
    ]
  }'
Example output:
rate limit exceeded
Step 3: Enable request-time token estimation
By default, agentgateway does not estimate token counts at request time. To reject requests before they reach the LLM, set tokenize: true on your model.
For more information about rate limiting configuration options, see Rate limits.
Add
tokenize: trueto the model’sparamsinconfig.yaml. Keep the existing provider credentials. Requests are rejected immediately if the estimated prompt tokens exceed the available budget.llm: models: - name: "*" provider: openAI params: apiKey: "$OPENAI_API_KEY" tokenize: trueSend a request. Use Bob’s virtual key because Alice’s virtual key already reached the rate limit in the previous step. This time, the request is rate limited because the estimated tokens exceed the budget.
curl http://localhost:4000/v1/chat/completions \
  -H 'Content-Type: application/json' \
  -H 'Authorization: Bearer vk-bob-8d1e7b' \
  -d '{
    "model": "gpt-3.5-turbo",
    "messages": [
      {
        "role": "user",
        "content": "Tell me a short story"
      }
    ]
  }'
Example output:
rate limit exceeded
Step 4: Give each key its own budget
So far, all of the virtual keys share one token budget, so the busiest key exhausts the budget for everyone else. To give each key its own budget, add a key field to the rate limit rule. The key field takes a CEL expression, and each distinct value that the expression returns gets its own token bucket with the limits of that rule. Use apiKey.user to read the user metadata from the authenticated key.
Add
key: apiKey.userto the rate limit rule. Removetokenize: truefrom the model to compare the result with Step 1. Keep the other authentication and model settings.llm: policies: localRateLimit: - maxTokens: 10 tokensPerFill: 1 fillInterval: 60s type: tokens key: apiKey.userRestart agentgateway with the updated configuration.
agentgateway -f config.yamlSend a prompt with Alice’s virtual key. The request is allowed, because Alice’s bucket is full after the restart.
curl http://localhost:4000/v1/chat/completions \
  -H 'Content-Type: application/json' \
  -H 'Authorization: Bearer vk-alice-4f9c2a' \
  -d '{
    "model": "gpt-3.5-turbo",
    "messages": [
      {
        "role": "user",
        "content": "Tell me a short story"
      }
    ]
  }'
Example output:
{
  "choices": [
    {
      "message": {
        "content": "Once upon a time, in a small village nestled between towering mountains...",
        "role": "assistant"
      },
      "finish_reason": "stop"
    }
  ],
  "usage": {
    "prompt_tokens": 12,
    "completion_tokens": 248,
    "total_tokens": 260
  }
}
Repeat the same request to exhaust Alice’s budget. The tokens that the first response used exceed the 10-token bucket, so this request is rate limited.
curl http://localhost:4000/v1/chat/completions \
  -H 'Content-Type: application/json' \
  -H 'Authorization: Bearer vk-alice-4f9c2a' \
  -d '{
    "model": "gpt-3.5-turbo",
    "messages": [
      {
        "role": "user",
        "content": "Tell me a short story"
      }
    ]
  }'
Example output:
rate limit exceededSend the same request with Bob’s virtual key. Unlike in Step 3, where Alice’s usage rate limited Bob, the request succeeds, because Bob’s key now has its own token bucket that Alice’s requests do not draw from.
curl http://localhost:4000/v1/chat/completions \
  -H 'Content-Type: application/json' \
  -H 'Authorization: Bearer vk-bob-8d1e7b' \
  -d '{
    "model": "gpt-3.5-turbo",
    "messages": [
      {
        "role": "user",
        "content": "Tell me a short story"
      }
    ]
  }'
Example output:
{
  "choices": [
    {
      "message": {
        "content": "Once upon a time, in a small village nestled between towering mountains...",
        "role": "assistant"
      },
      "finish_reason": "stop"
    }
  ],
  "usage": {
    "prompt_tokens": 12,
    "completion_tokens": 248,
    "total_tokens": 260
  }
}
Review the following behavior before you rely on a keyed budget.
- Keys that cannot be evaluated: Requests whose key is empty, or whose expression cannot be evaluated, such as an unauthenticated request when the key reads
apiKey.user, all share one bucket. An empty key does not exempt a request from the limit. - How many buckets are kept, and where they live: Each rule keeps up to 65,536 buckets and drops the least used ones, which for that key is the same as never having been seen. Buckets are held in memory by a single agentgateway instance, so each instance enforces the limit separately. For a virtual key whose bucket was dropped, the next request starts from a full bucket. For a budget that is shared across instances, use remote rate limits.
For more information, including how to key a limit on a JWT claim or on the requested model, see Per-key limits.
Monitor per-key spending
Usage tracking is optional and does not require a token budget.
Agentgateway exposes token usage as Prometheus metrics on its stats endpoint, which listens on port 15020 by default (not the 15000 admin port). The agentgateway_gen_ai_client_token_usage metric is a histogram that records the tokens used per request.
By default, this metric is broken down by dimensions such as the model (gen_ai_request_model) and token type (gen_ai_token_type), but not by key. To attribute usage to each virtual key, add a label such as user_id that reads the user metadata from the authenticated key, then query Prometheus.
Note
The token usage metric only appears after a request succeeds and the LLM returns a usage count. Requests that are rejected (for example, a 401 from an invalid key or a 429 from the rate limit) never reach the LLM, so they do not produce token usage metrics.
Add a per-key metric label
You can add a per-key metric label such as to track metrics by user ID. Note that the user_id label is high cardinality: every unique value creates a new metric series, which increases Prometheus memory and storage. This is acceptable for tens or hundreds of keys, but avoid attaching unbounded identifiers at large scale. Prefer lower-cardinality dimensions like tier or team when possible.
Update your configuration to add a
user_idmetric label. Theaddfield maps a label name to a CEL expression that is evaluated per request. UseapiKey.userto read theusermetadata from the authenticated key. Add this block toconfig.yamlwithout replacing the existing authentication or budget policies.config: metrics: fields: add: user_id: apiKey.userSetting Description config.metrics.fields.addA map of metric label names to CEL expressions. Each expression is evaluated per request and its result is attached as a Prometheus label on the metrics. user_id: apiKey.userAdds a user_idlabel whose value is theusermetadata from the authenticated API key. If the expression cannot be evaluated (for example, on an unauthenticated request), the label value isunknown.Restart agentgateway with the updated configuration, then send successful requests with each key so the metrics have per-key data to report. Because the earlier rate-limit budget is small, raise
maxTokensor wait for the bucket to refill so the requests are not rejected.Verify that the
user_idlabel is attached to the token usage metric. Read the metrics endpoint and filter for the token usage sum.curl -s http://localhost:15020/metrics | grep gen_ai_client_token_usage_sumEach series now carries a
user_idlabel that matches theusermetadata of the key that made the request. For example, after sending requests with Alice’s and Bob’s keys:agentgateway_gen_ai_client_token_usage_sum{gen_ai_token_type="input",gen_ai_request_model="gpt-3.5-turbo",...,user_id="alice"} 21.0 agentgateway_gen_ai_client_token_usage_sum{gen_ai_token_type="output",gen_ai_request_model="gpt-3.5-turbo",...,user_id="alice"} 14.0 agentgateway_gen_ai_client_token_usage_sum{gen_ai_token_type="input",gen_ai_request_model="gpt-3.5-turbo",...,user_id="bob"} 9.0 agentgateway_gen_ai_client_token_usage_sum{gen_ai_token_type="output",gen_ai_request_model="gpt-3.5-turbo",...,user_id="bob"} 9.0
Query with Prometheus
The raw curl output in the previous step is a quick sanity check, but it returns only Prometheus exposition text. To run aggregations such as totals over time or estimated cost, use PromQL. PromQL runs inside a Prometheus server that scrapes the agentgateway metrics endpoint. You cannot send PromQL to the /metrics endpoint directly, so in standalone mode you run your own Prometheus.
Create a Prometheus scrape configuration that targets the agentgateway stats endpoint.
cat <<'EOF' > prometheus.yml
global:
  scrape_interval: 5s

scrape_configs:
- job_name: agentgateway
  static_configs:
  - targets: ["host.docker.internal:15020"]
EOF
Note
Use
host.docker.internal:15020when you run Prometheus in Docker, as in the next step. If you run the Prometheus binary directly on your machine, uselocalhost:15020instead.Start Prometheus with this configuration.
docker run --rm -p 9090:9090 \
  -v "$(pwd)/prometheus.yml:/etc/prometheus/prometheus.yml" \
  prom/prometheus
Verify that Prometheus is scraping agentgateway. Open http://localhost:9090/targets and confirm that the
agentgatewaytarget is UP. You might need to restart the container or refresh the page.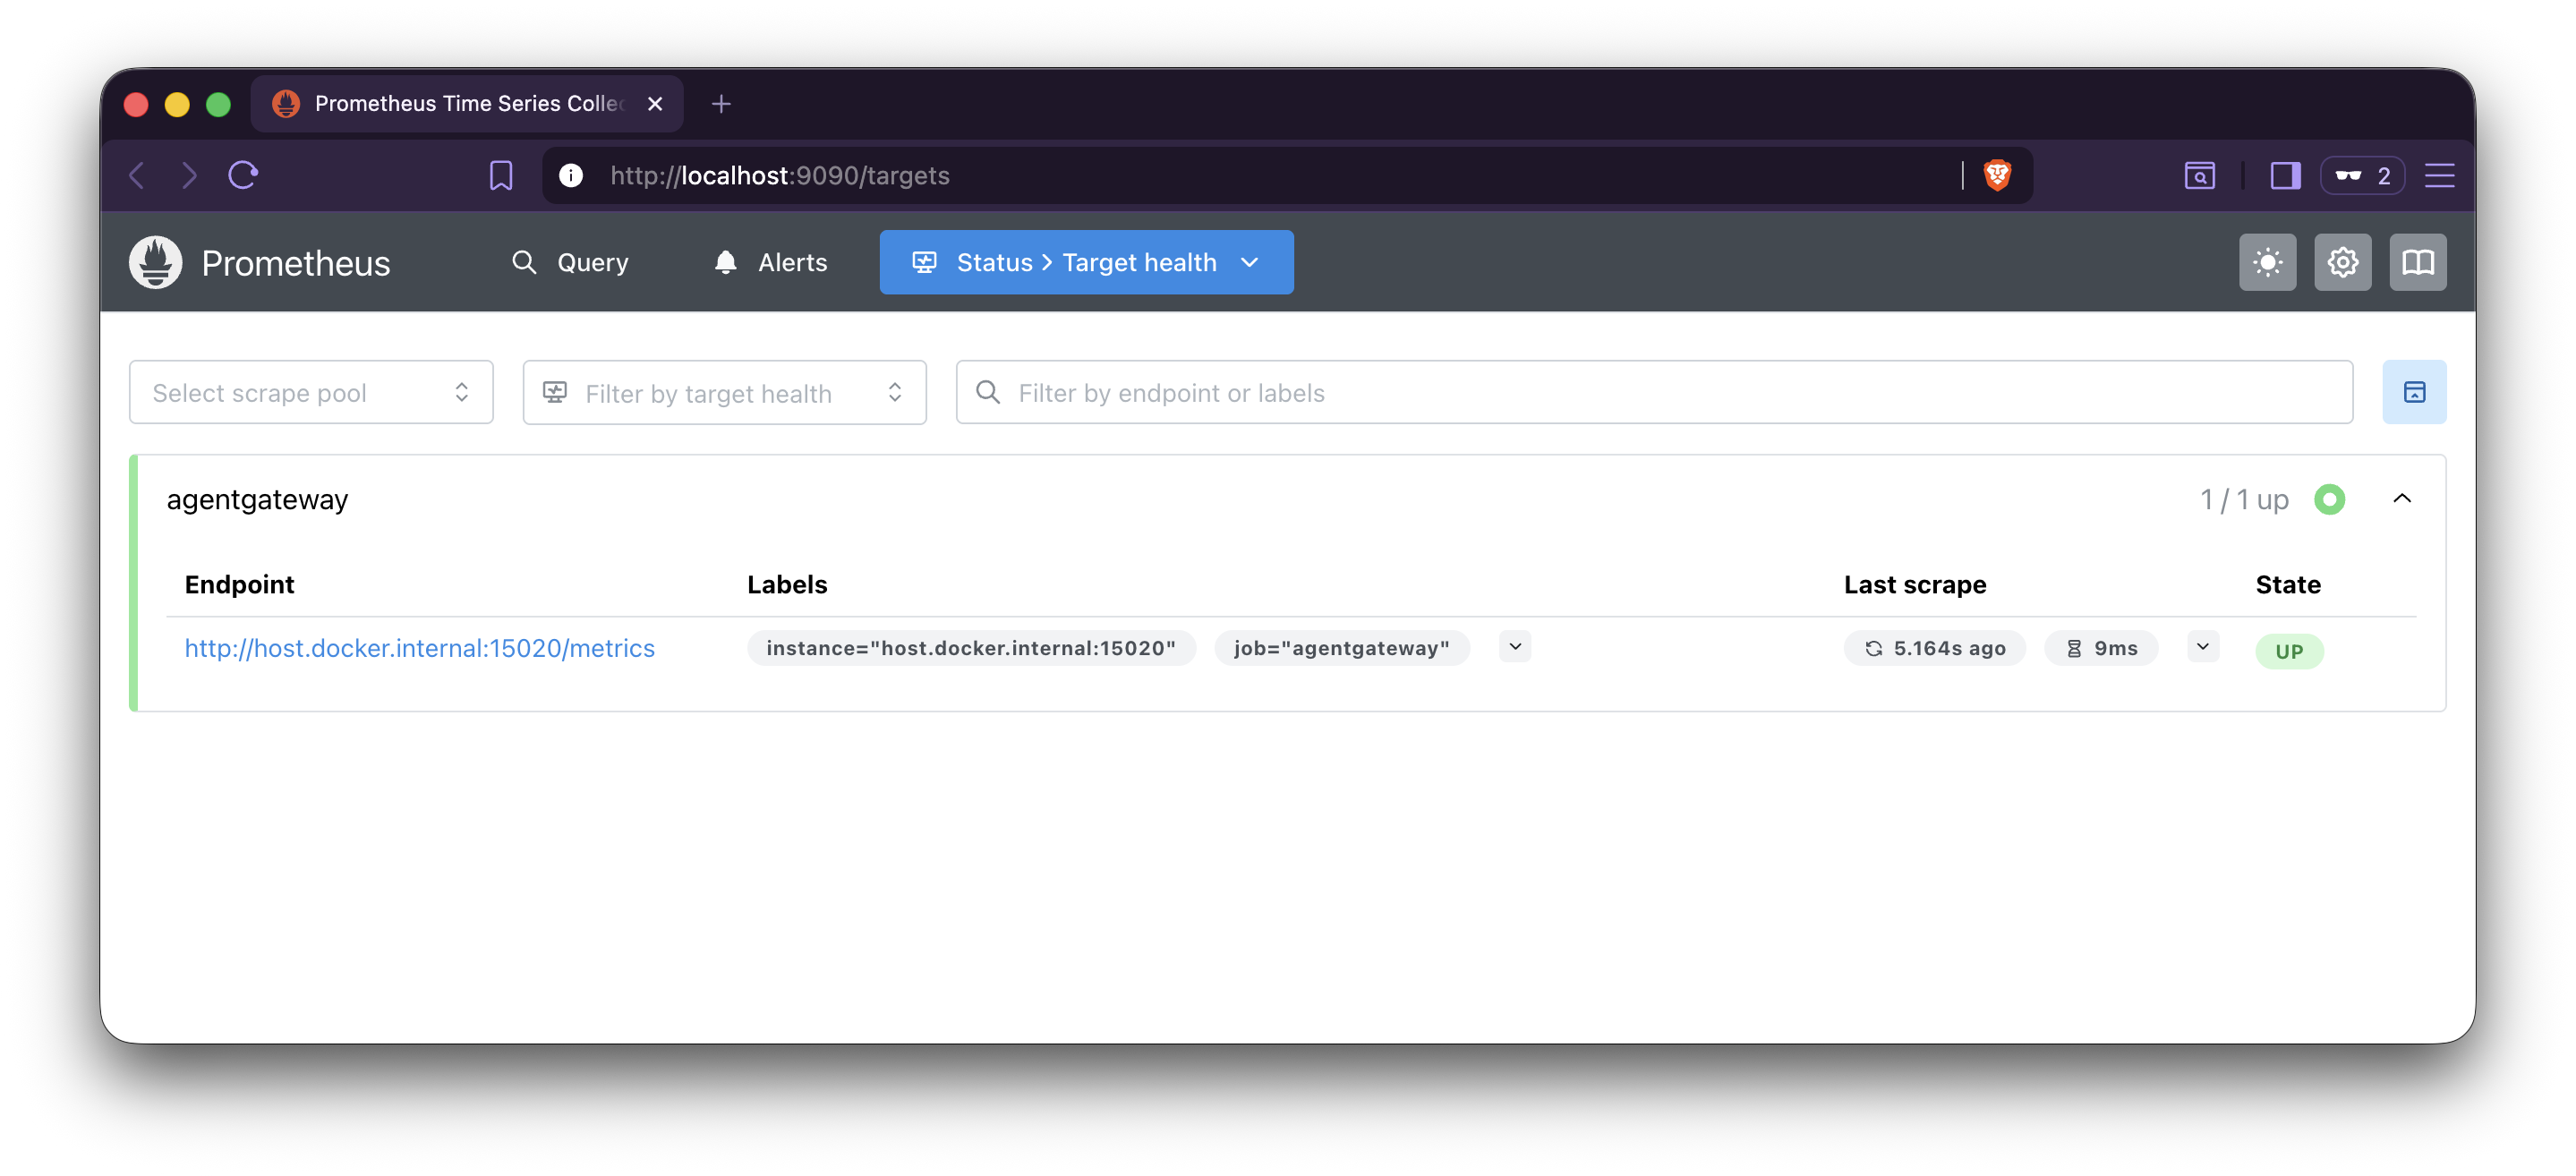
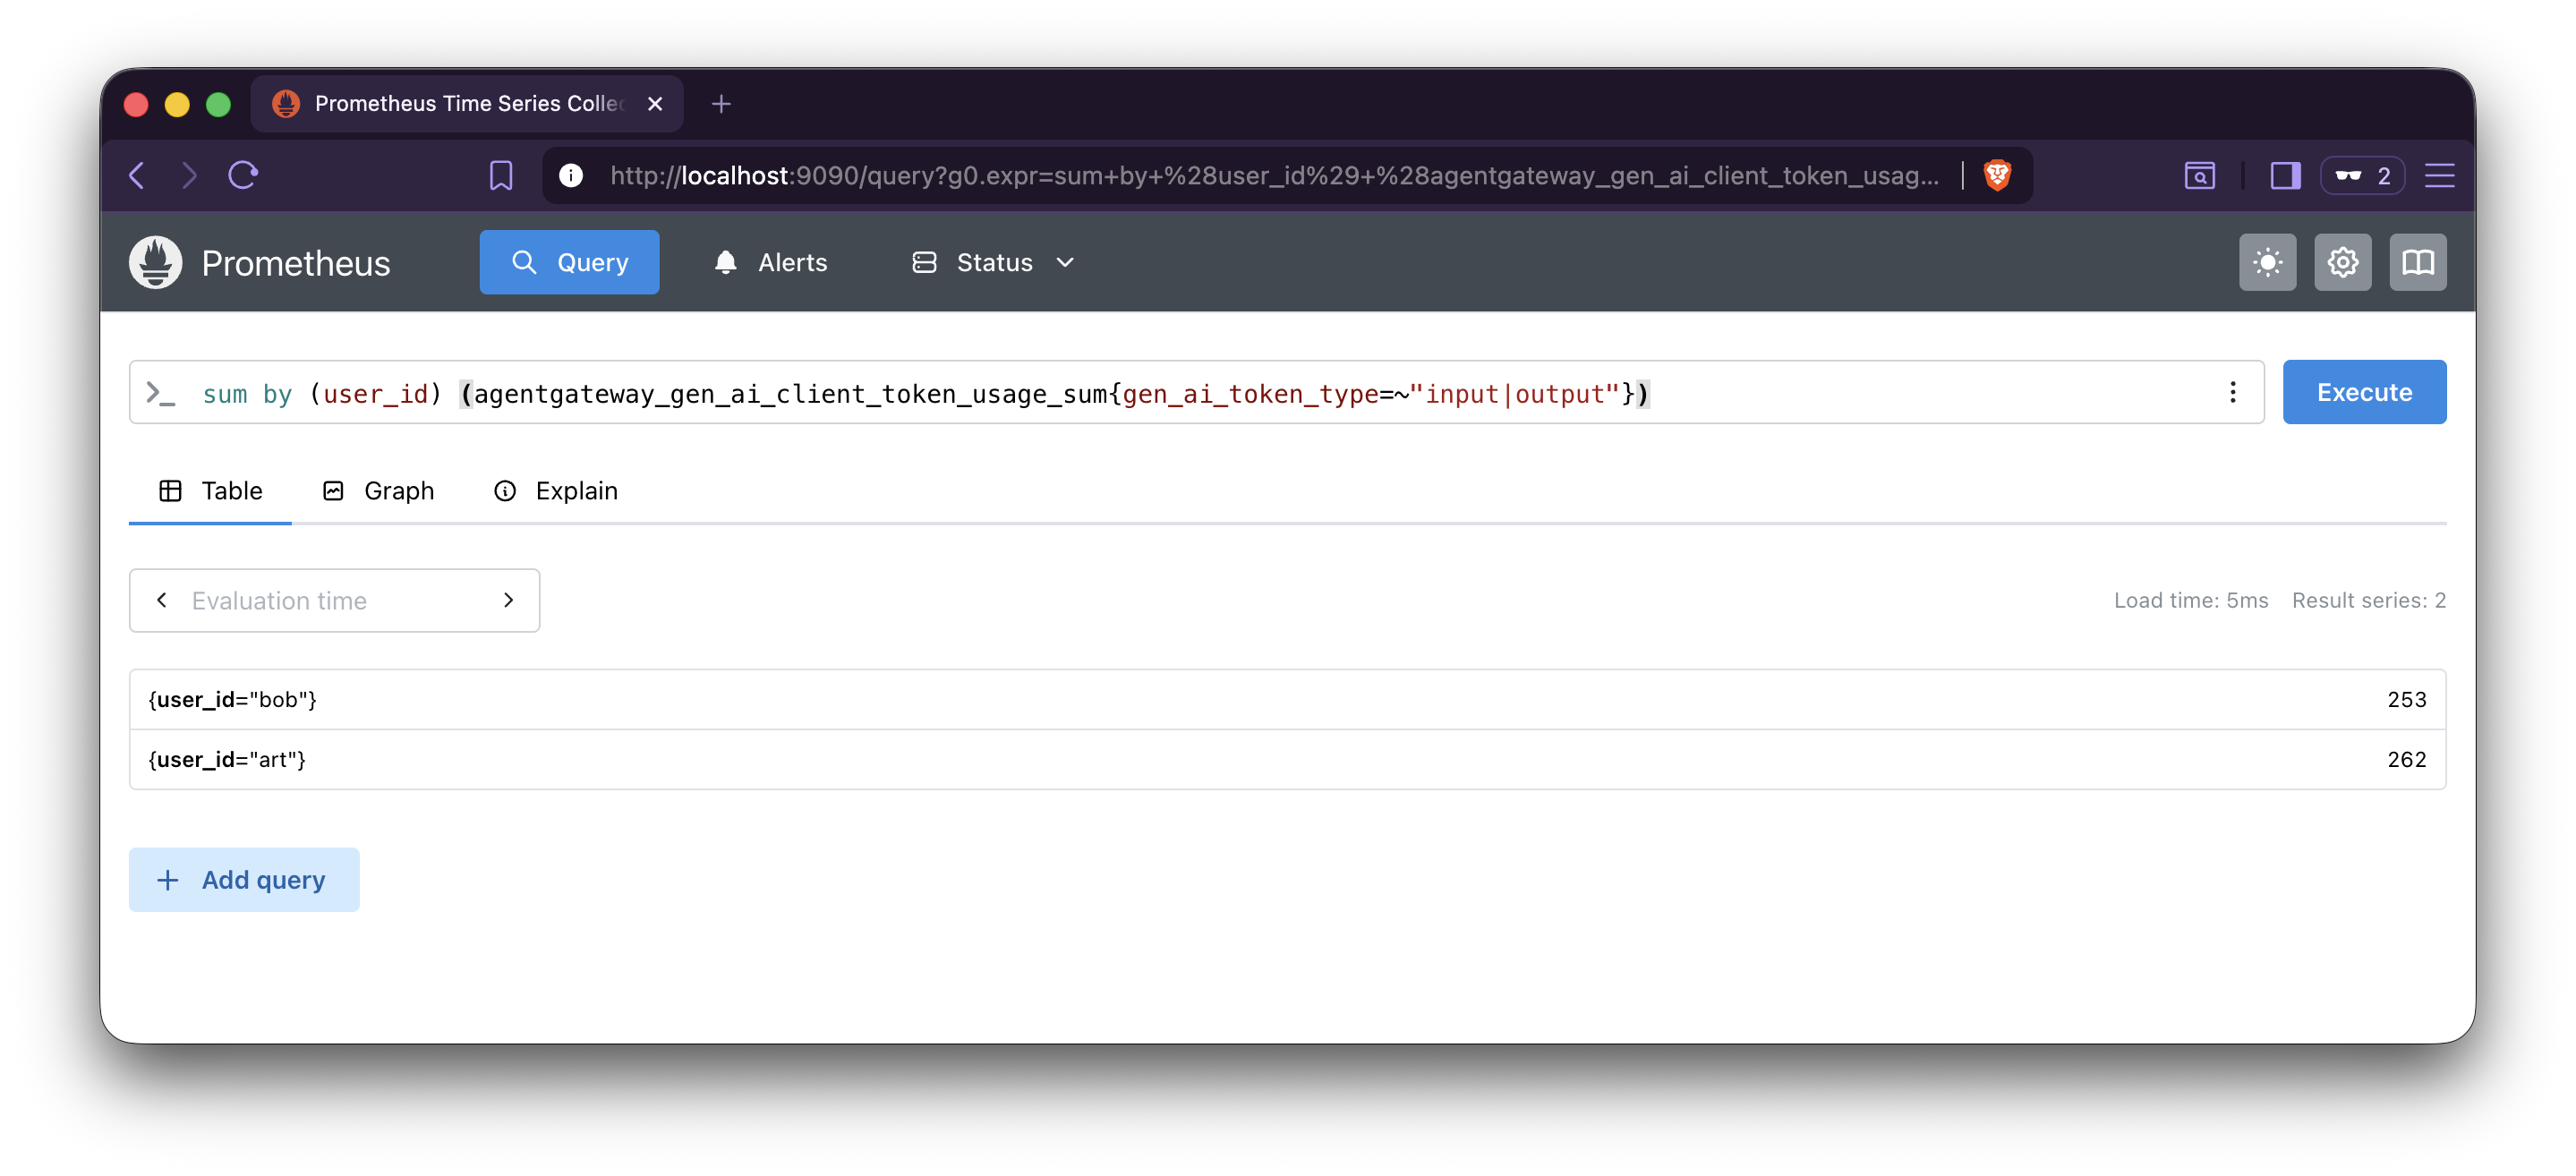
Query token usage per key. The following query returns the total tokens consumed by each virtual key. The token usage metric carries a separate series per token type, so match both
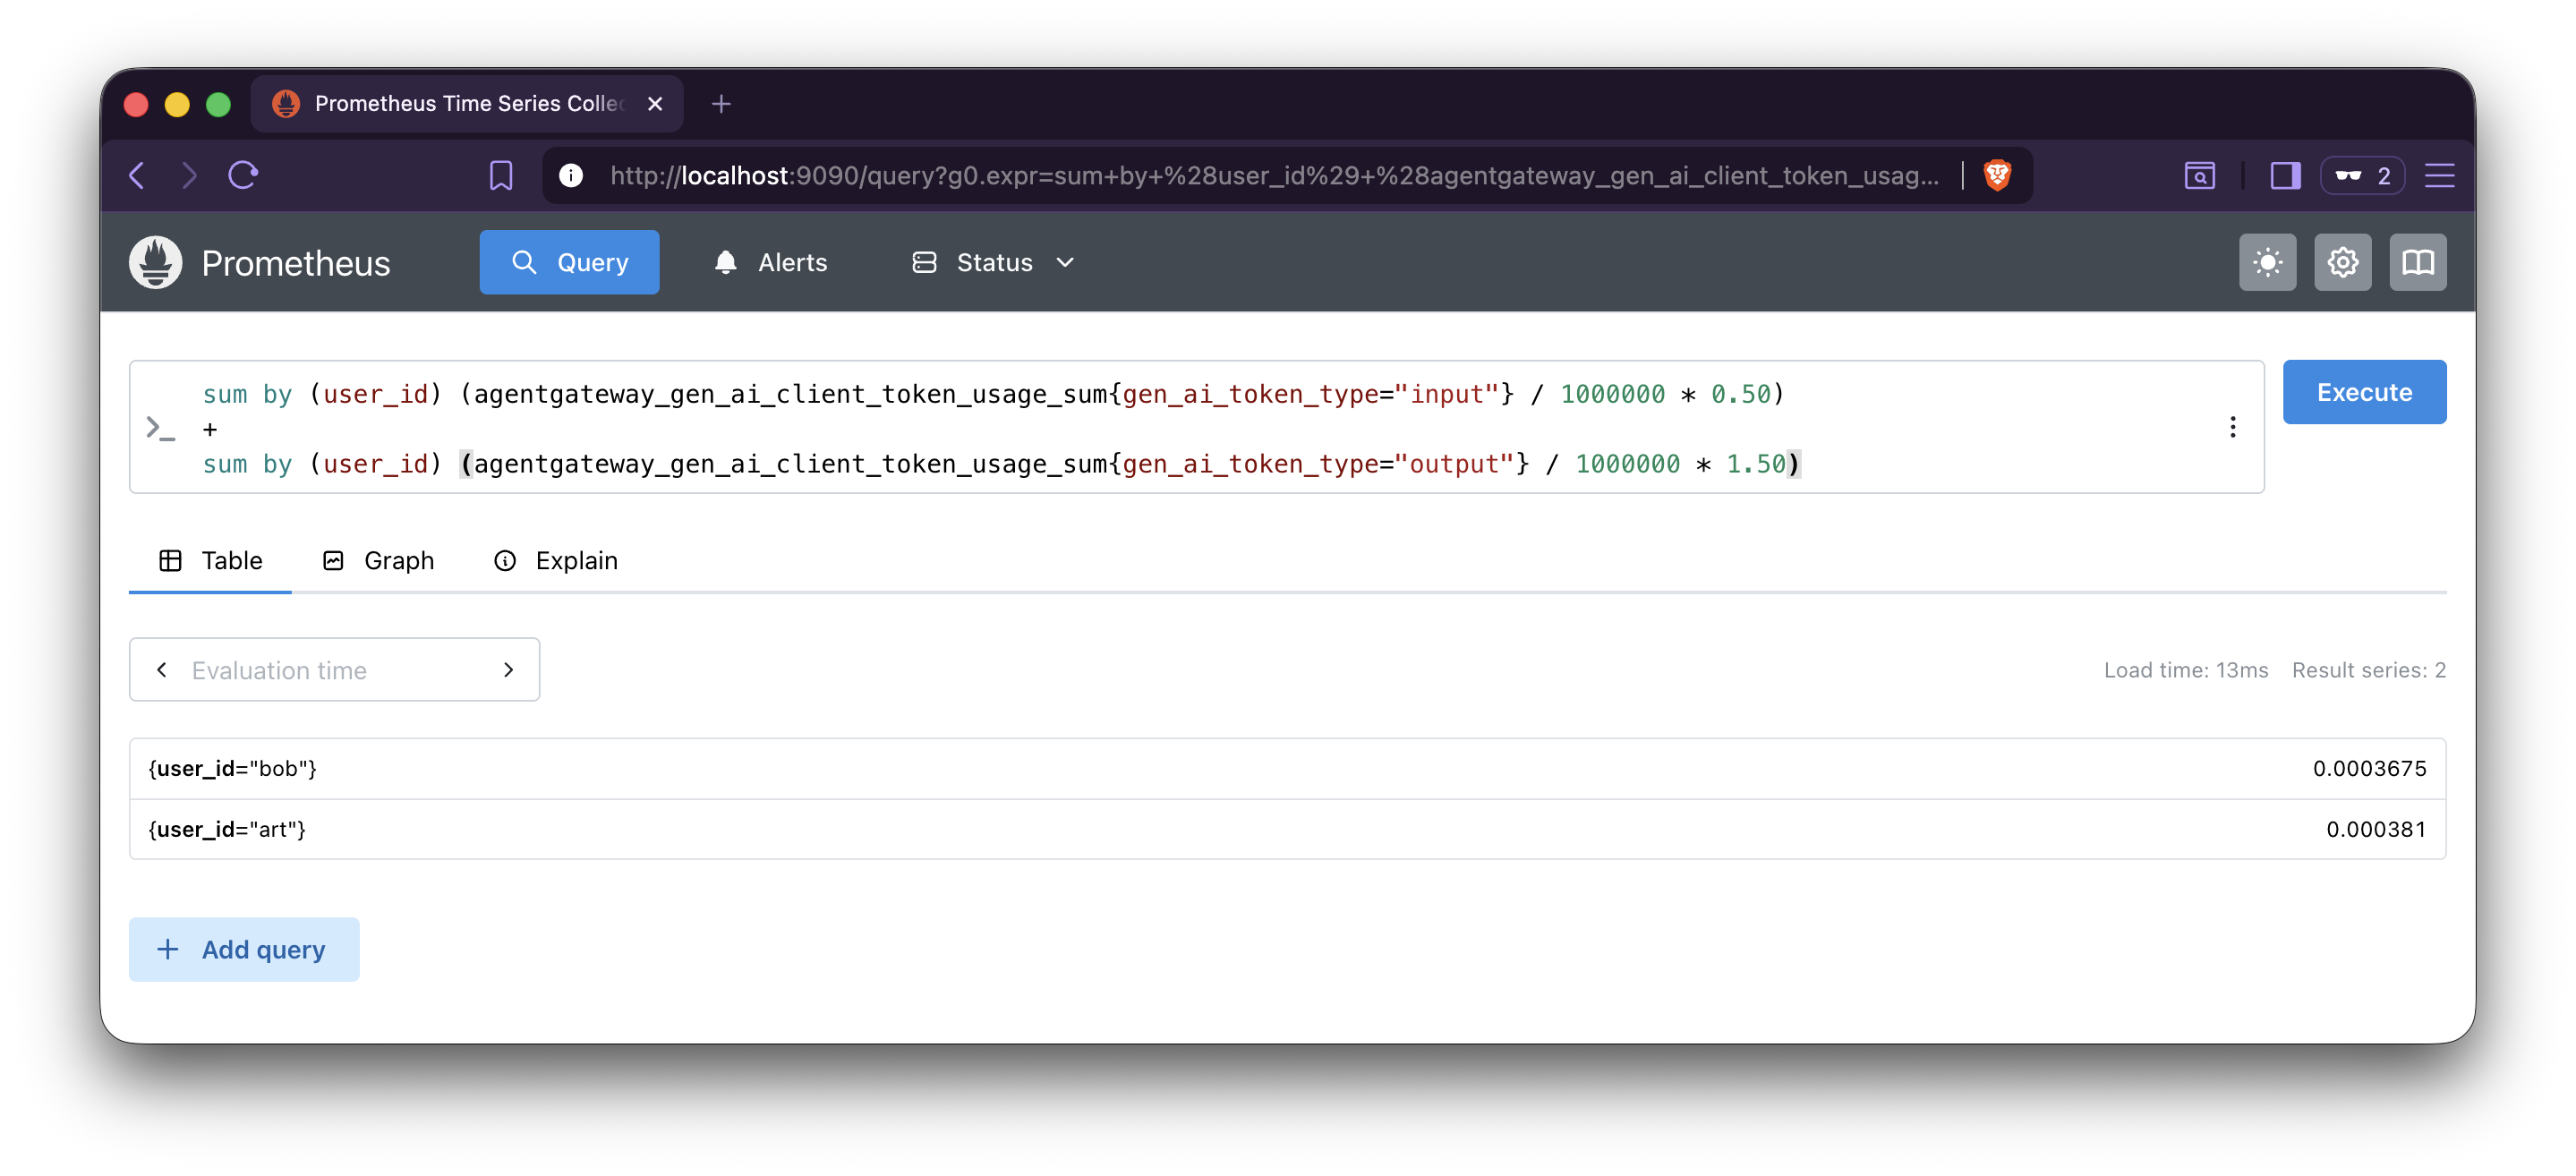
inputandoutputin a single selector with=~and sum them.sum by (user_id) (agentgateway_gen_ai_client_token_usage_sum{gen_ai_token_type=~"input|output"})Estimate costs by multiplying token counts by your provider’s pricing. Input and output tokens are usually priced differently, so aggregate each type separately, then add the two results. Each
sum by (user_id)collapses thegen_ai_token_typelabel, so the+matches onuser_id.Note
Queries that use
rate()orincrease()over a range such as[24h]need that much scrape history to return meaningful values. While testing locally, query the raw_sumcounters or use a shorter range such as[5m].This query estimates cost for OpenAI GPT-3.5 by applying your own pricing to token counts. To have agentgateway compute the realized USD cost per request from a model cost catalog, see Model costs.
# Estimated cost per key (assuming $0.50 per 1M input tokens, $1.50 per 1M output tokens)
sum by (user_id) (agentgateway_gen_ai_client_token_usage_sum{gen_ai_token_type="input"} / 1000000 * 0.50)
+
sum by (user_id) (agentgateway_gen_ai_client_token_usage_sum{gen_ai_token_type="output"} / 1000000 * 1.50)